Embodied AI models
Inside SLIP-VLA’s Single-Step Latent Look Ahead
SLIP-VLA is a proposed vision-language-action policy framework intended to make future modeling more efficient for robot control.
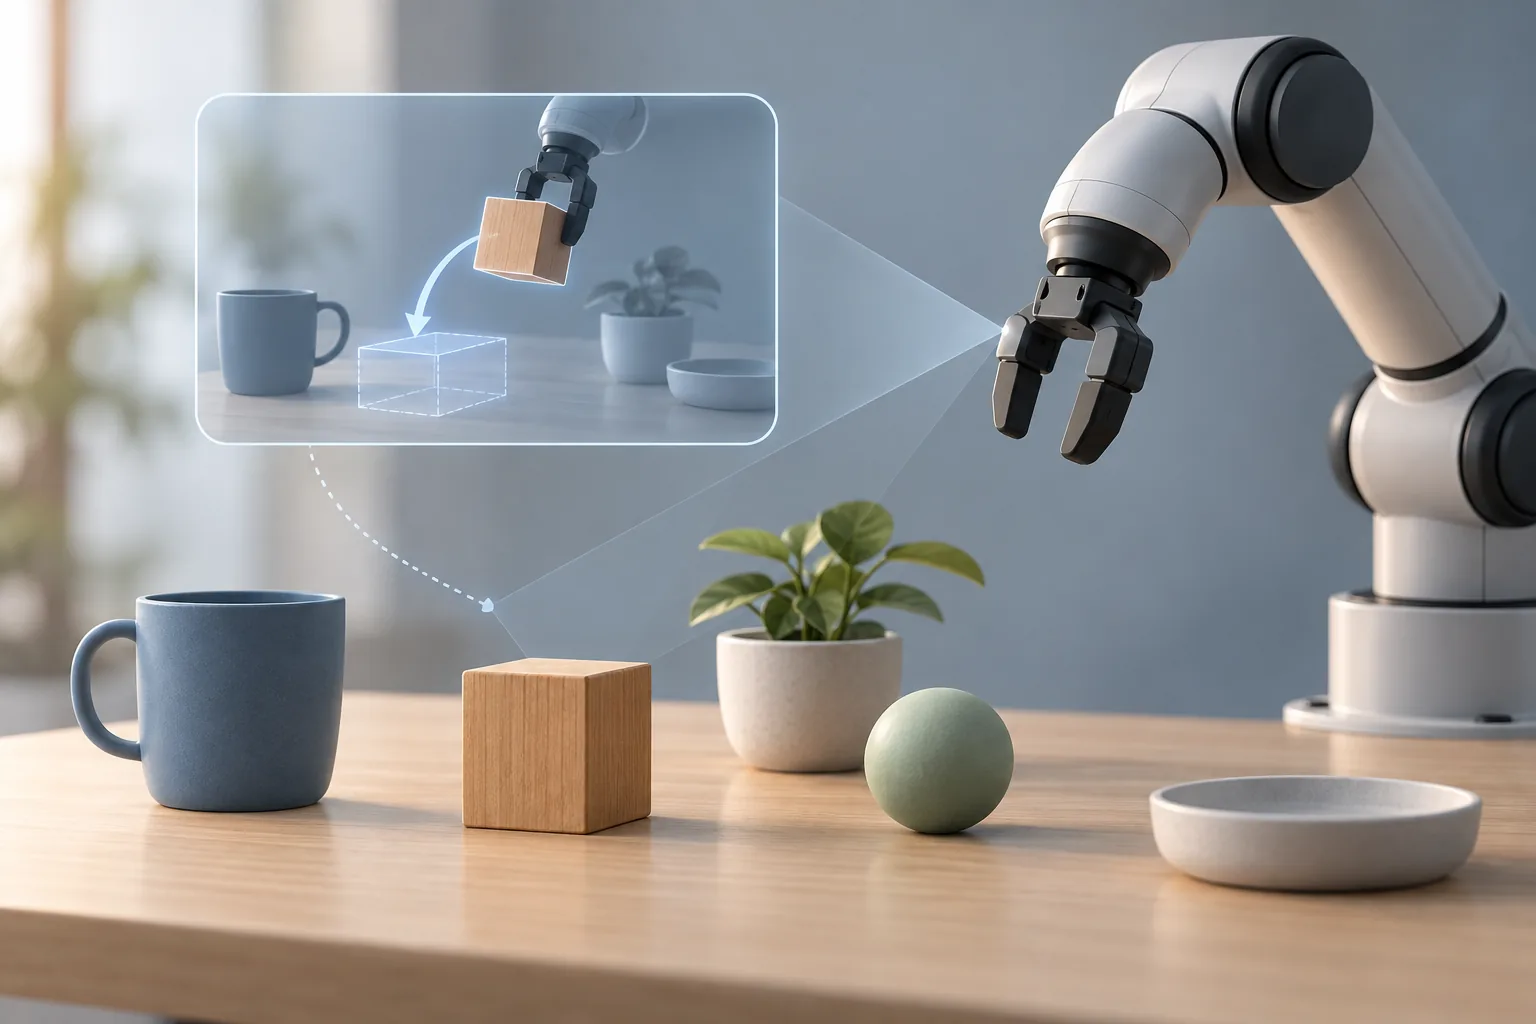
SLIP-VLA predicts ahead by producing temporally dense future latent representations with one denoising update, then uses those internal features for future-aware action prediction.
To retain useful visual information, the framework aligns intermediate latents with future geometric and semantic features. The authors present this alignment as a way to improve perceptual sufficiency, meaning that the representation preserves information about the scene’s future structure and meaning for the policy.
The design also connects the imagined transition to control. The framework uses action-conditioned latent world modeling and inverse dynamics modeling, explicitly coupling latent transitions with robot actions.
In the arXiv preprint abstract submitted on September 27, 2026, the authors report state-of-the-art performance across simulation benchmarks and real-world manipulation tasks, and they say the single-step latent imagination takes 12 ms. The admitted excerpt does not identify the individual benchmarks, metrics, baselines, hardware timing conditions or task-level results, so those claims cannot be independently assessed from this evidence alone.
The supported contribution is a proposed way to make future-aware action prediction more efficient by moving the forecast into an action-linked latent representation.