Research updates
TERRA Uses Compact Temporal Effects and EAT to Preserve Latent-Action Meaning
A preprint combines a compressed account of visual change with cross-context alignment so that an inferred action code is defined by what it does, not only where it came from.
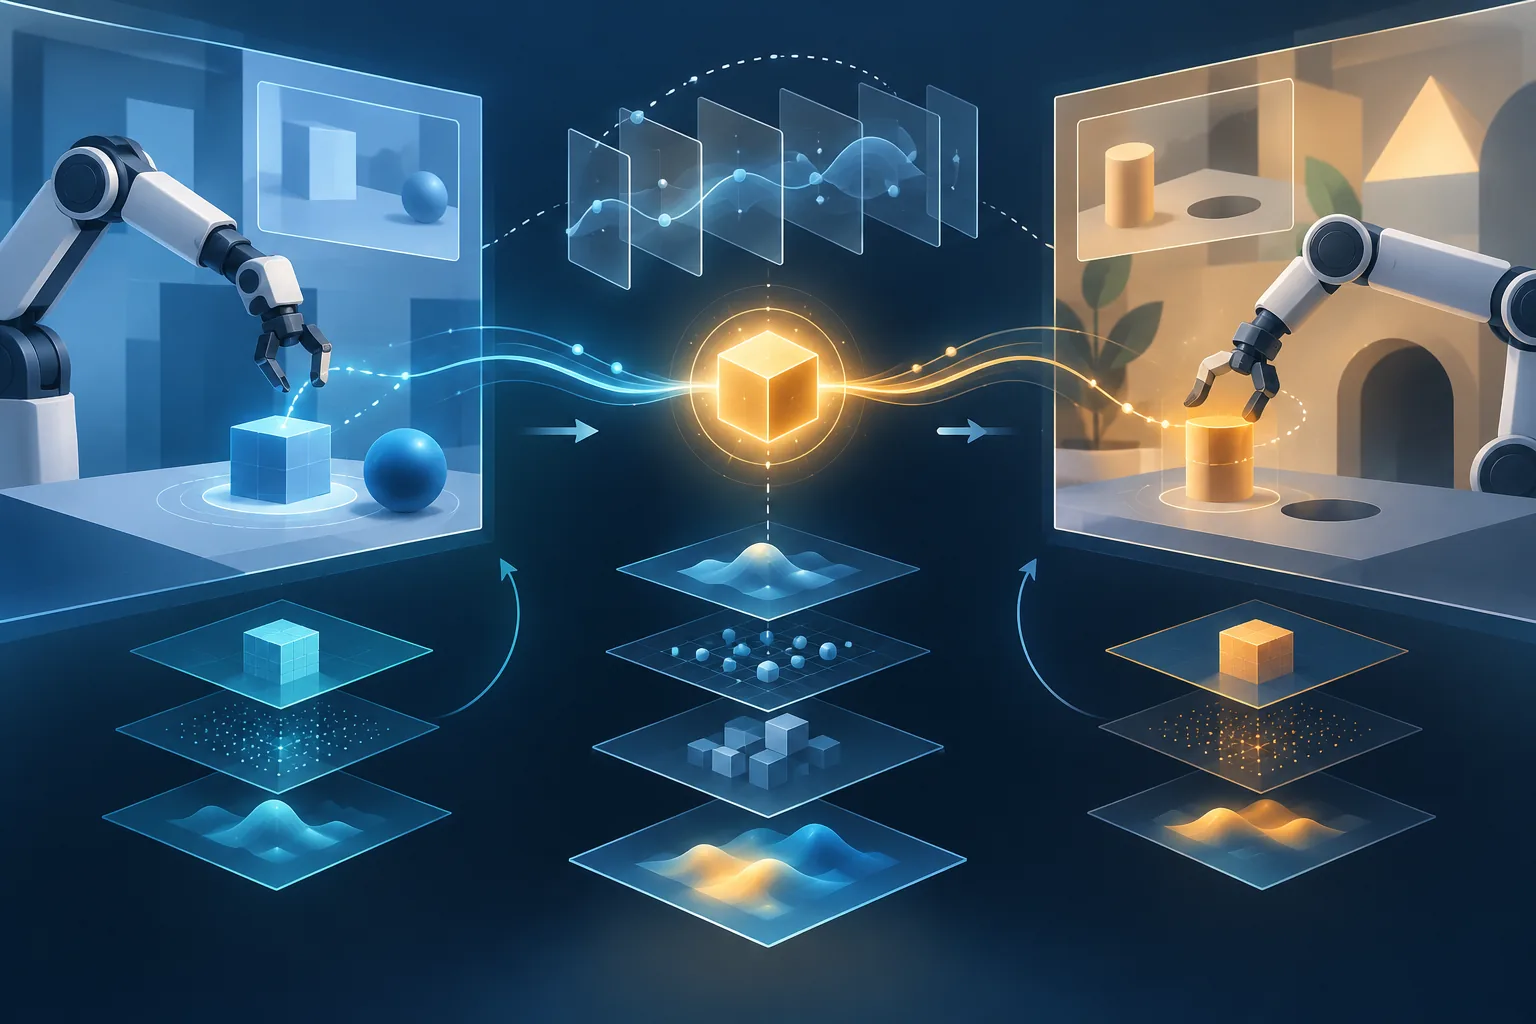
In TERRA, a latent robot action keeps its meaning across different starting states by tying it to a compact temporal effect and anchoring the effect produced from another state to the effect observed at its source. A latent action is an action-like code inferred from a visual transition.
The preprint represents each transition through its net change in visual features plus a low-order description of how those features evolve within the time window. Its authors argue that an endpoint difference alone loses the course of the motion, while retaining the full sequence also preserves distracting variation. The compact representation is intended to keep information from both without storing the entire sequence.
Effect-Anchored Transport, or EAT, supplies the cross-context constraint. EAT decodes a latent in other initial states and anchors the resulting effect to the one observed at its source, so the latent is shaped by what it does across contexts rather than only by the transition it came from. This addresses the limitation of reconstruction training, which observes a latent only with the state it came from.
The authors report that frozen linear readers predict actions more accurately with TERRA than with UniVLA and a LAPA-style baseline. They also report slower degradation under visual distractors, greater fidelity to the donor action as the recipient context becomes more different and a same-budget control indicating that much of the gain comes from EAT. At matched pretraining scale, the complete system achieved 93.4% average success on LIBERO, compared with 91.8% for UniVLA. These results come from the TERRA preprint and are not independent confirmation.