Embodied AI models
How GTA-VLA Uses Visual Cues to Steer Robot Decisions
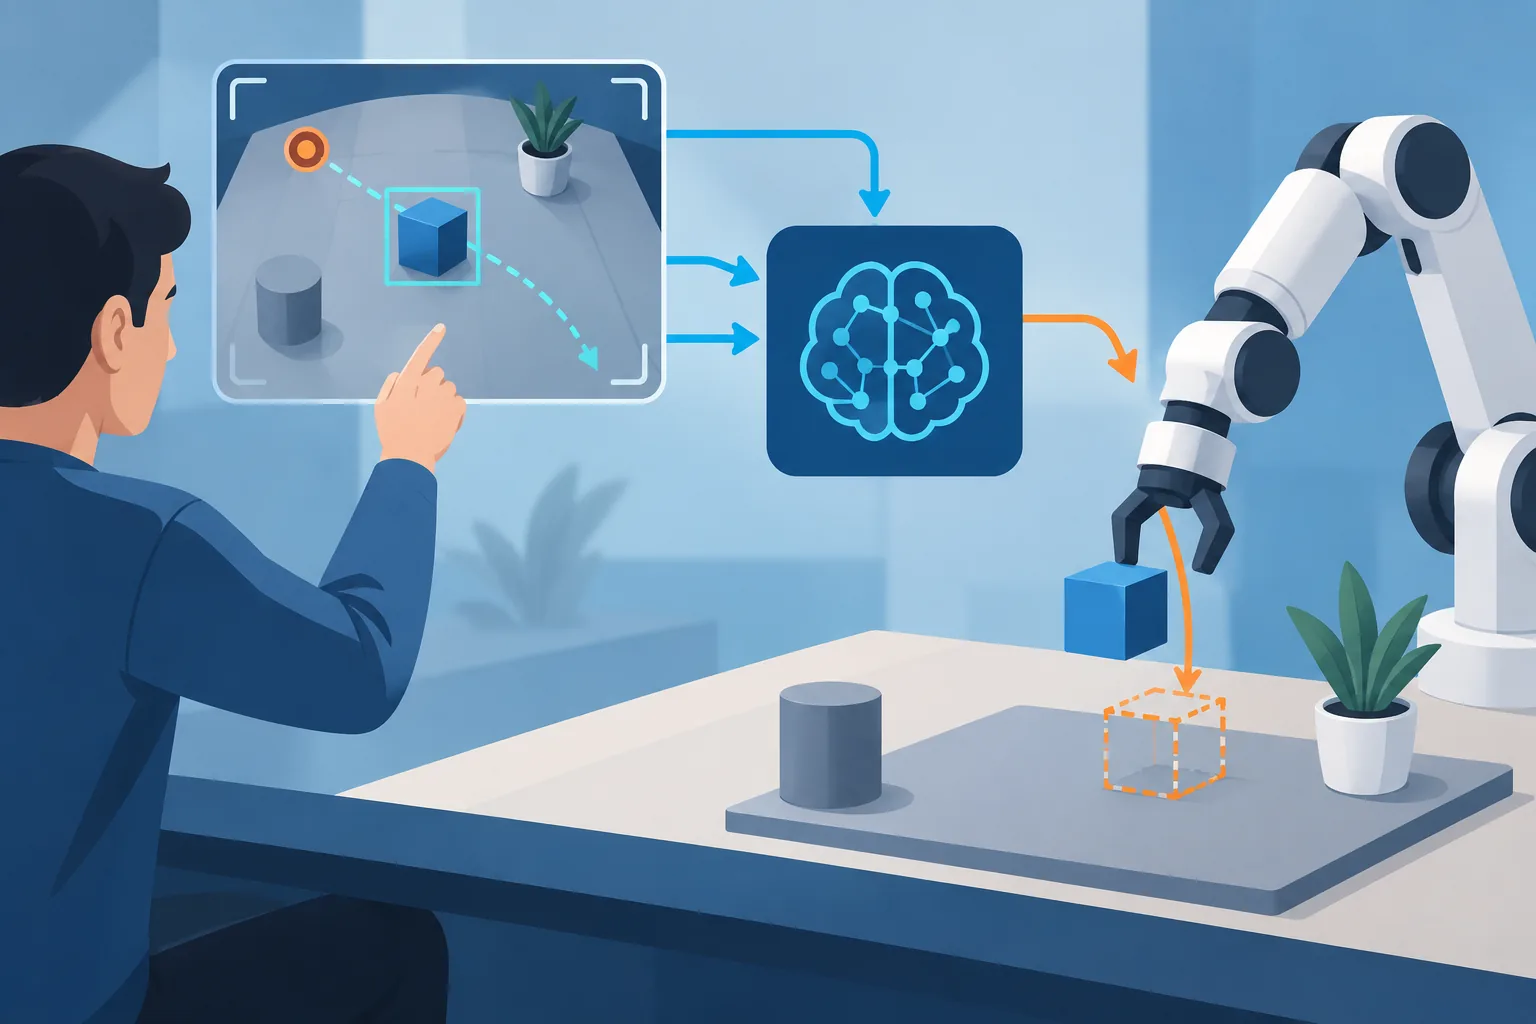
The GTA-VLA authors propose optional human visual guidance for policy reasoning and a lightweight reactive head for action execution.
Visual cues can guide a robot policy by supplying optional spatial priors that shape its intermediate reasoning before a separate reactive head executes actions.
The authors contrast this process with the direct “Sense-to-Act” mapping used by existing vision-language-action models, which turn multimodal observations into robot commands. They present human spatial guidance as a way to resolve visual ambiguities or recover from mistakes.
The authors report an 81.2% success rate on the in-domain SimplerEnv WidowX benchmark and say that one visual interaction substantially improved task success under out-of-domain visual shifts and spatial ambiguities compared with existing methods. The supplied excerpt gives no improvement magnitude for those shifted conditions, physical-robot result or independent confirmation, so the findings support the proposed mechanism without establishing its real-world performance.