Embodied AI models
CompVLA gives vision-language-action robots variable stiffness
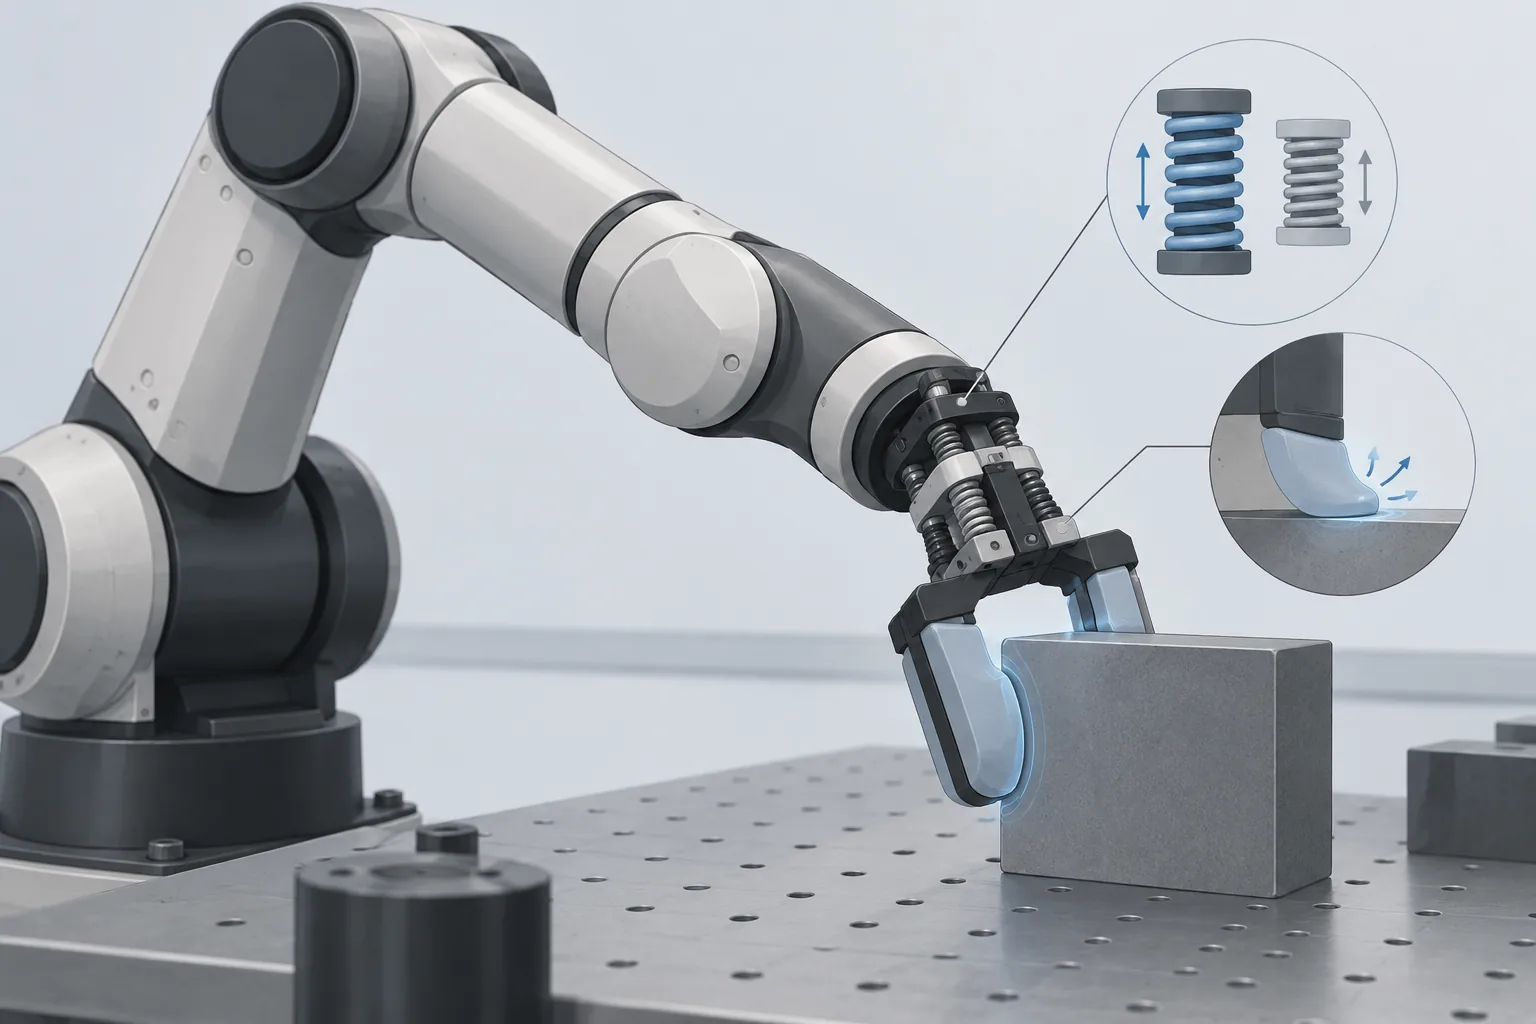
CompVLA is a proposed vision-language-action architecture for regulating robot compliance during contact-rich manipulation.
A vision-language-action robot can adjust its compliance by jointly predicting motion and a stiffness matrix from RGB images and language, then executing time-varying stiffness and virtual displacement profiles through geometric impedance control.
The CompVLA preprint’s authors report the highest average success rate across diverse contact-rich tasks when comparing their system with both conventional and compliance-aware VLA baselines. They also say ablation experiments found every component essential. The available evidence is the authors’ abstract, so these comparative results are author-reported claims rather than independent confirmation.