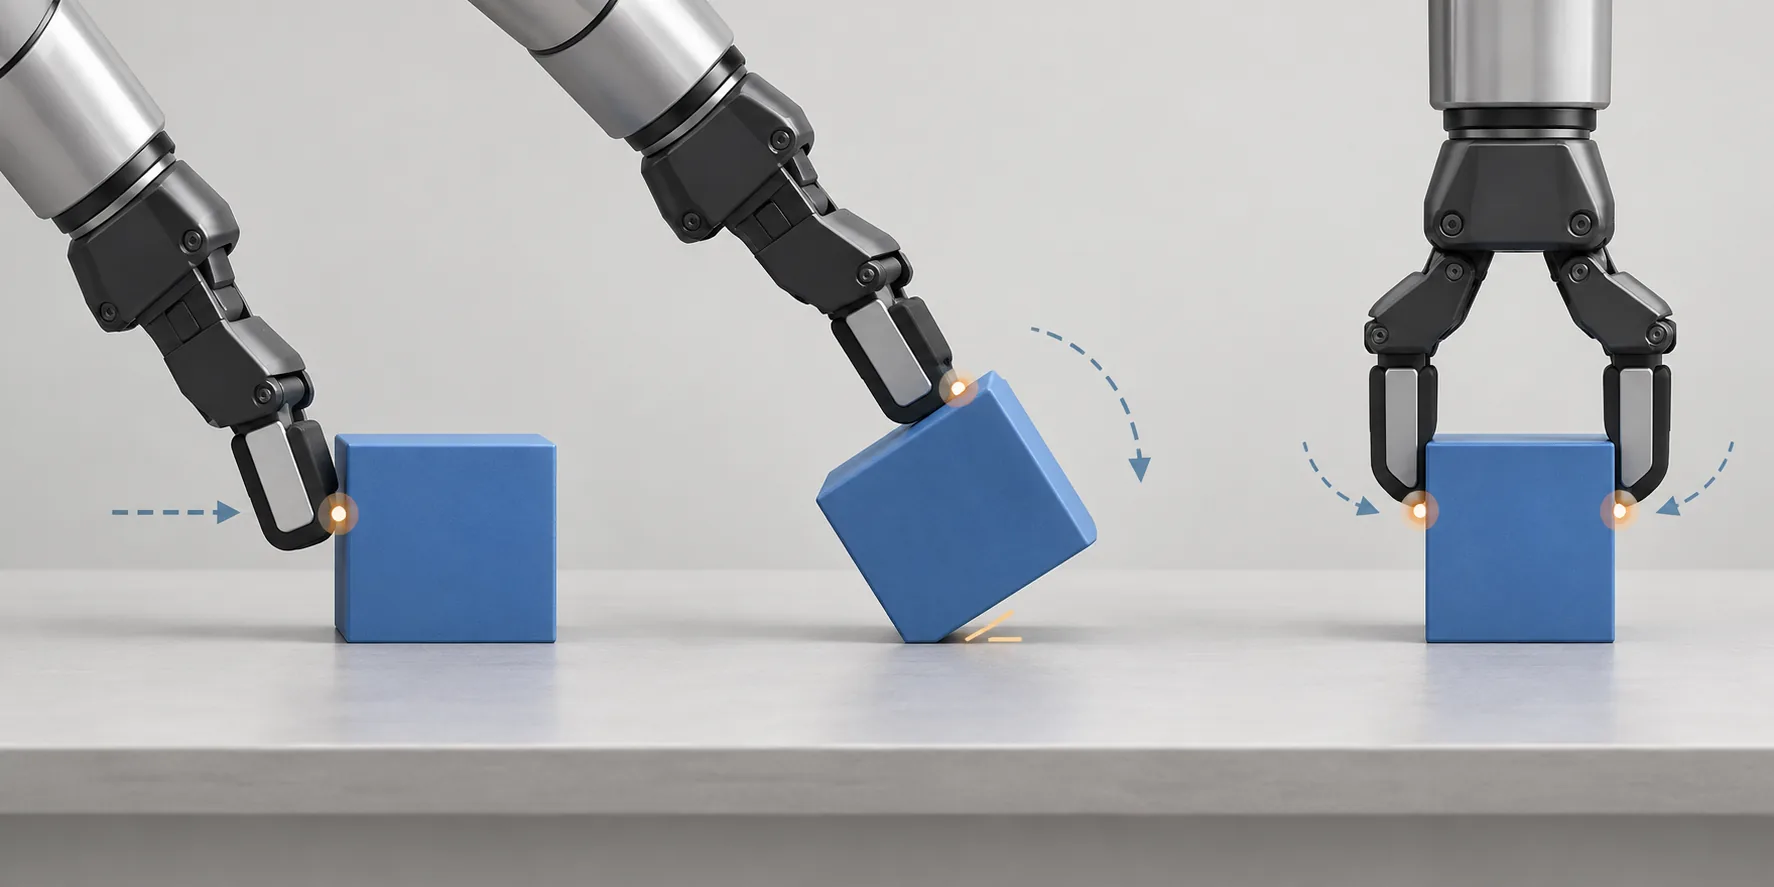
Uni-PNP: Unified Prehensile and Non-prehensile Policy Learning
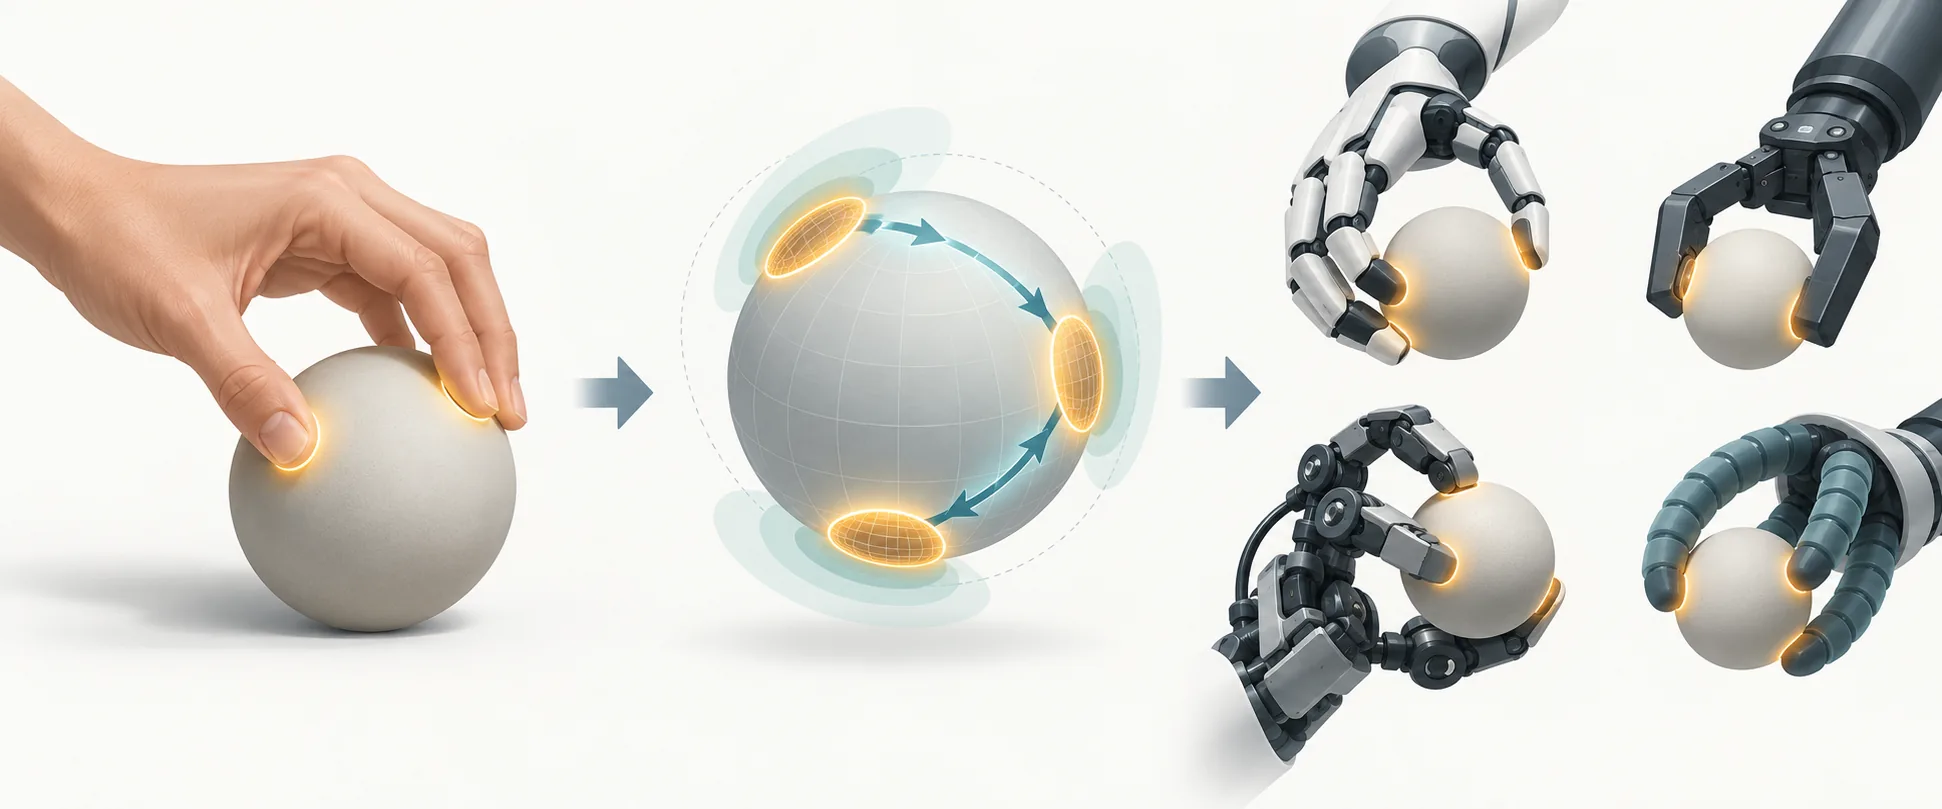
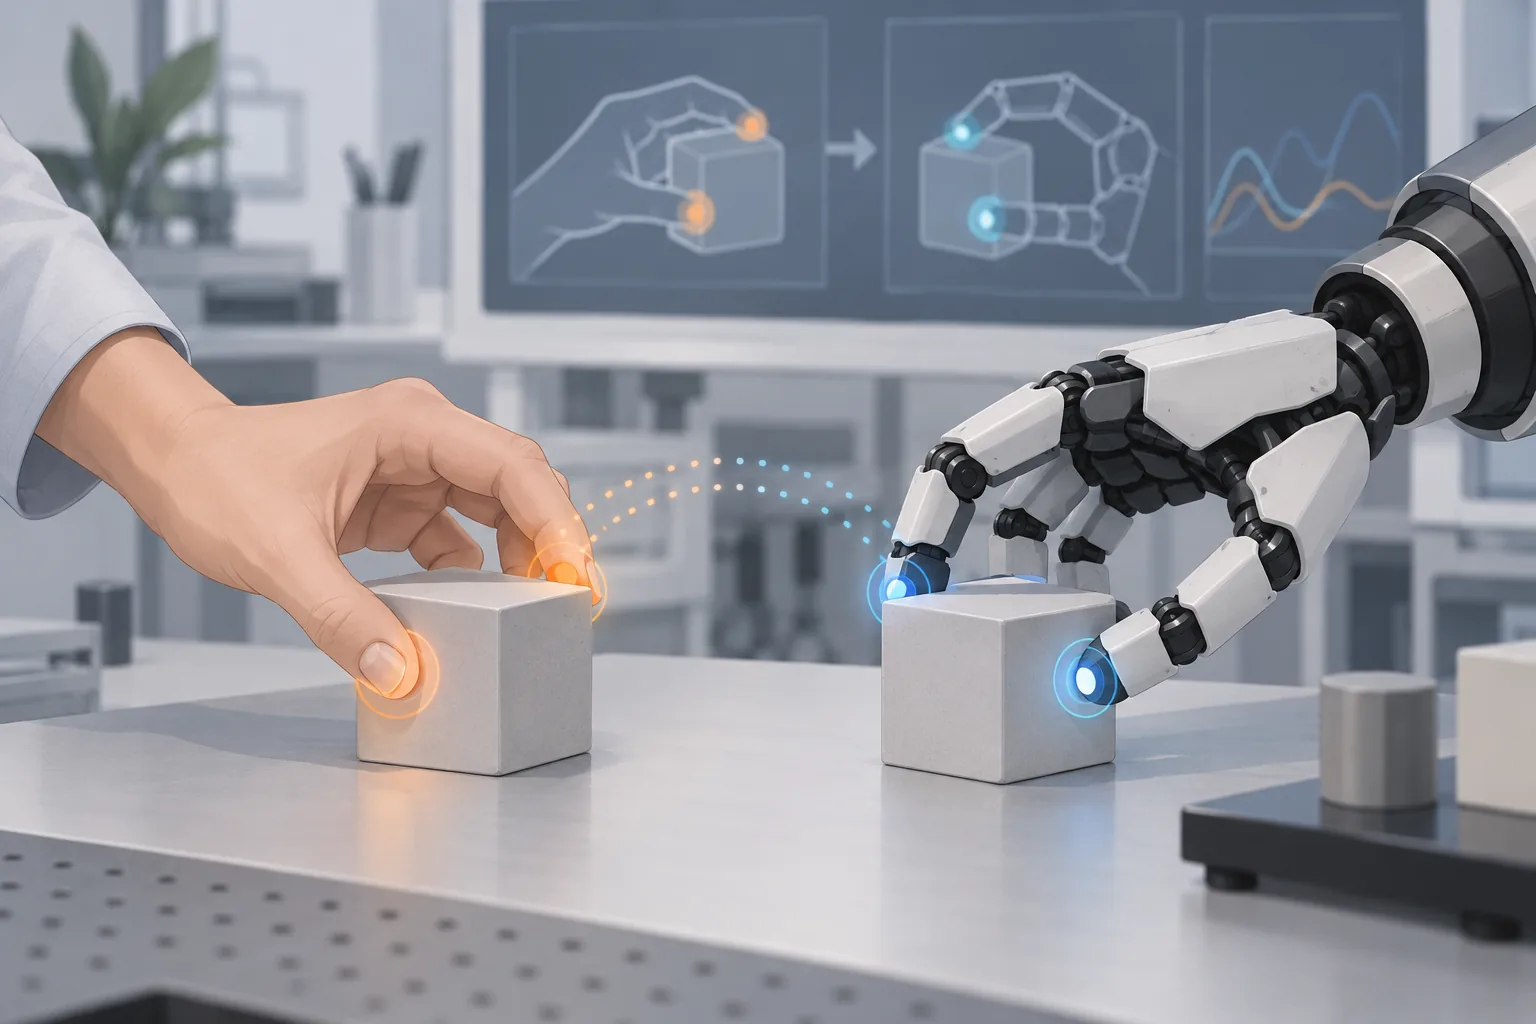
Uni-PNP learns a unified object-pose-reaching policy by modeling contact-induced motion and progressing from graspable to ungraspable objects during reinforcement learning. Its authors report gains on seen and unseen objects, while providing only an unspecified claim of real-world transfer in the available abstract.
Published