Learning methods
Train Robots Where the Challenge Is Just Right
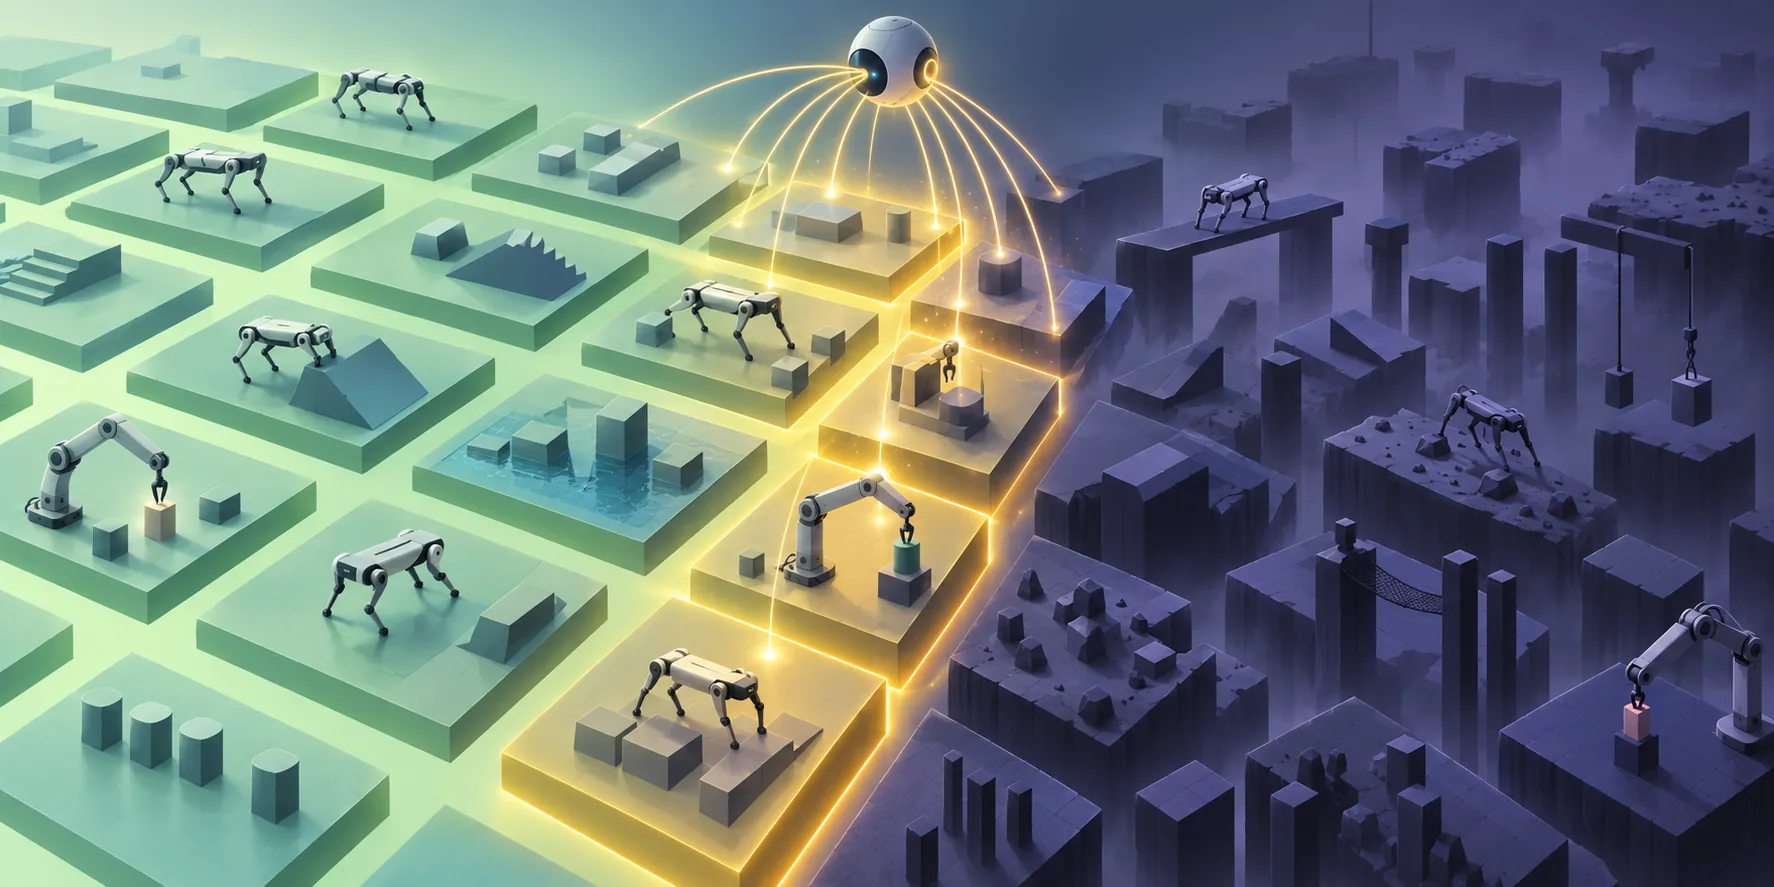
An adaptive sampler reallocates simulated practice toward a robot policy’s capability frontier, aiming to preserve useful learning signal as parallel training grows.
Uniform sampling across a broad range of simulator resets can spend much of a training batch on configurations that a robot policy has already mastered or cannot yet tackle. Success Guided Sampling focuses robot reinforcement learning by adaptively selecting simulated task configurations near the boundary between what the current policy can already complete and what it cannot yet attempt. This capability frontier offers practice that is neither redundant nor currently out of reach, preserving more of the batch’s learning signal as parallel simulation expands.
The abstract reports experiments using up to $2^{20}$ (over one million) parallel environments. In those experiments, SGS enabled reinforcement learning to solve multi-terrain quadruped locomotion and contact-rich assembly tasks that prior methods failed to solve. It also reports distilling the learned manipulation policies into RGB-based policies and demonstrating zero-shot transfer to several assembly tasks on real hardware.
The available abstract describes the training scale, task settings and hardware demonstrations, but it does not supply task-level success rates or comparative measurements. Its supported practical lesson is specific: when uniform sampling spends learning experience on configurations the policy has mastered or cannot yet attempt, sampling around the policy’s capability frontier can make better use of the experience in a training batch.