Data and benchmarks
How to Test Robot Value Feedback Reliability
The preprint brings fine-grained execution checks together with model evaluations under standard conditions and separate shifts in robot embodiment and environment.
The preprint says existing evaluations cover only selected aspects of execution understanding, leaving the reliability of value feedback insufficiently tested.
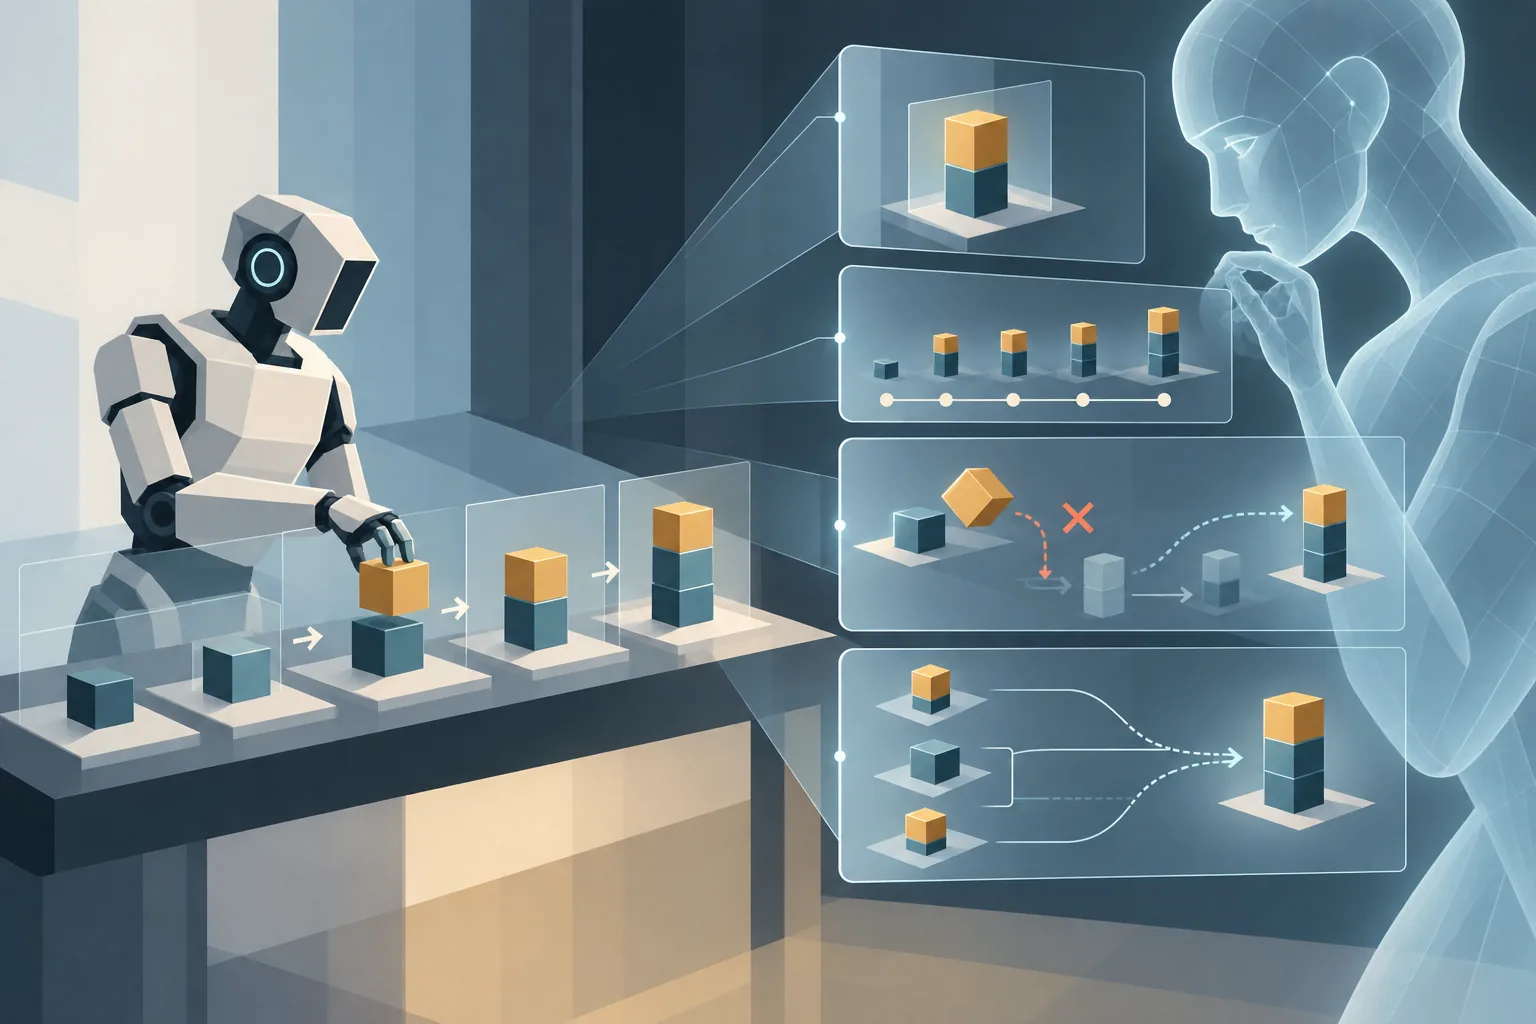
The framework evaluates four complementary capability dimensions through shared interfaces. Diagnostic trajectories and instruction variations test whether value judgments reflect task requirements and changes throughout execution. Comparing valid execution orders tests value consistency, because the authors report that the same semantic subtask can receive substantially different value gains across those orders.
The evaluation should also vary the model's operating conditions. The preprint reports tests of representative models in zero-shot and one-shot settings under standard conditions and under separate shifts in robot embodiment and environment. The dataset covers 15 simulation tasks and 20 real-world manipulation tasks, with expert demonstrations for training and annotated trajectories for fine-grained evaluation.
These targeted checks matter because the authors report instruction-grounding errors, history-dependent progress-tracking errors, and poor recovery assessment even among models with strong outcome and forward-progress scores. The practical test of reliable feedback is therefore not a single aggregate score, but a set of controlled probes that can reveal where and when the model's judgment changes. These findings come from the RoboValue preprint and should not be treated as independent confirmation of the benchmark or the evaluated models.