Data and benchmarks
How Visual Ablations Expose Task Priors in Robot Evaluation
Capability-level scores and matched visual ablations can show whether correct answers track observed task progress or survive on learned action expectations.
A model may answer a question about a robot task correctly without interpreting how the observed activity has unfolded. To distinguish temporal understanding from a plausible guess, an evaluation must test separate capabilities and measure how answers change when the visual evidence is withheld.
Separate the capabilities
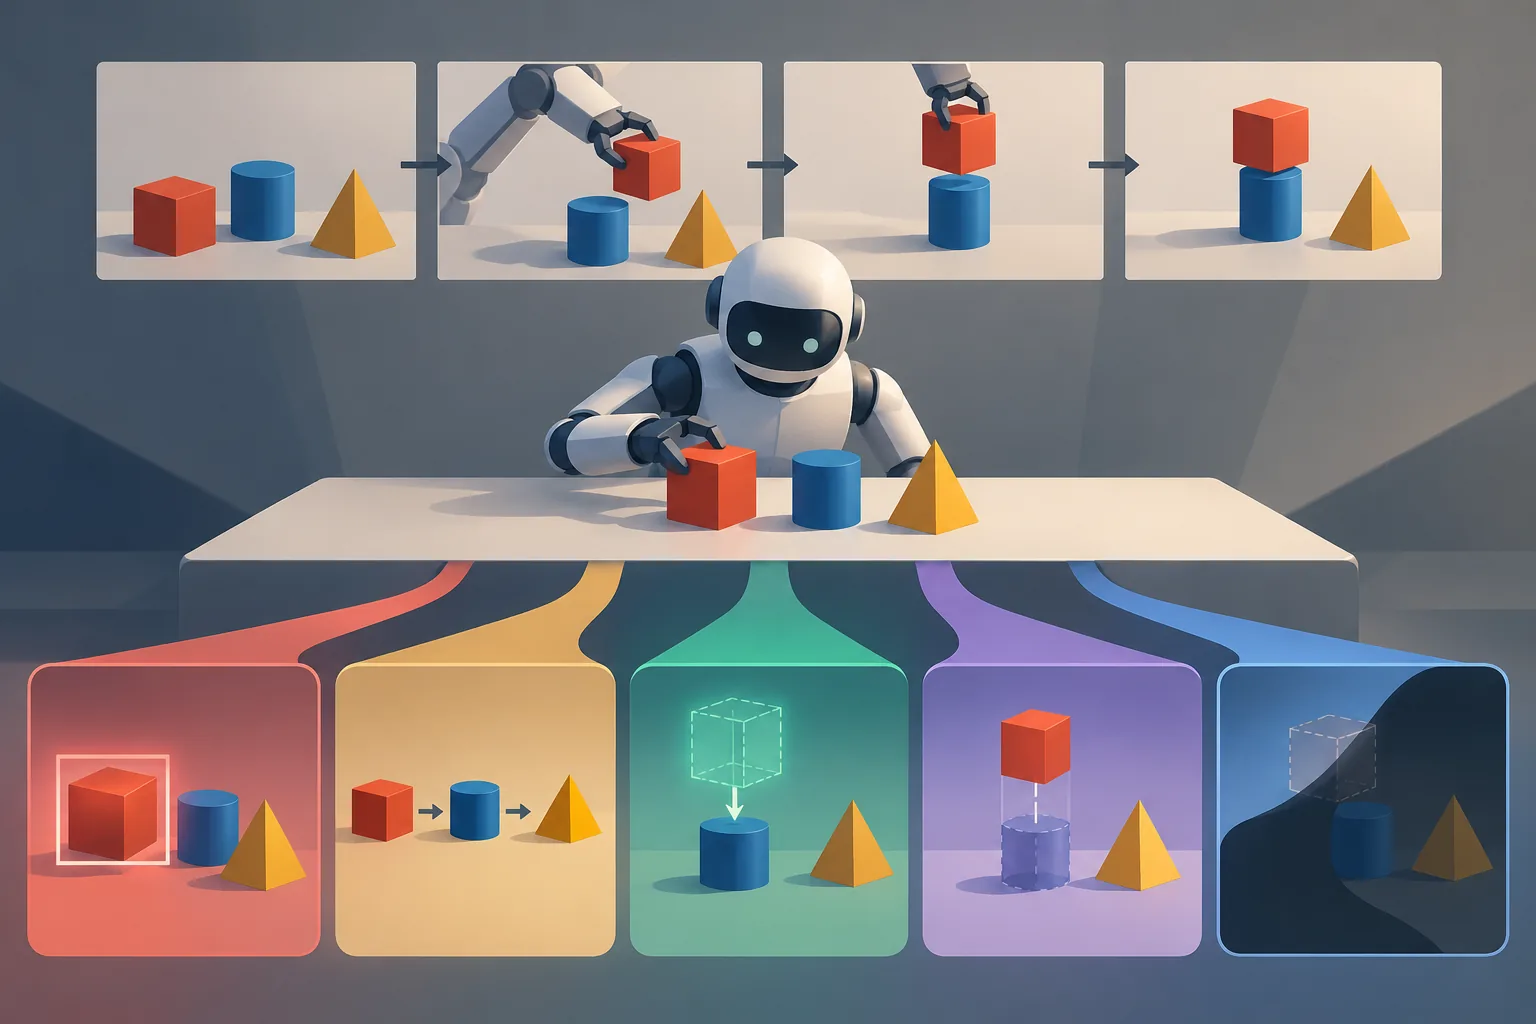
RoboChrono’s authors describe a benchmark built from real-robot executions and complementary bare-hand human recordings, with 39 scenarios and 34,713 evaluation instances. Its seven tasks are grouped into recognition, alignment, and temporal grounding, covering action understanding and anticipation, visual correspondence, temporal ordering, and action localization. Reporting these capabilities separately prevents success on one test from concealing weakness on another.
The authors’ zero-shot evaluation of 18 vision-language models illustrates why that separation matters. GPT-6-Astra recorded 98.3% accuracy on Frame Matching but 68.3% on Frame Ordering. RynnBrain1.1-122B-A10B reached 95.4% and 32.9%, respectively. In this reported evaluation, identifying matching frames therefore did not establish that a model could recover their temporal order.
Remove the observations
A benchmark can expose reliance on task priors by reporting capability-specific scores and repeating matched questions after removing the visual observations. The reported input ablation used five open-weight models. Removing the observations reduced Current Action Recognition accuracy by 22.1 percentage points, while Next Action Prediction fell by only 0.7 points.
That contrast measures dependence on the input rather than accuracy alone. The authors interpret the small change in next-action prediction as evidence that models can use learned task or action priors when visual evidence is unavailable, whereas recognizing the current action depends more strongly on the observations. A useful diagnosis therefore combines disaggregated task scores with matched visual ablations: ordering failures reveal that correspondence is not enough, and ablation sensitivity shows whether a correct answer is tied to the unfolding scene.
These results come from the benchmark authors’ preprint abstract, not an independent replication. The available evidence supports the diagnostic design and the reported aggregate comparisons, but not conclusions about every scenario or model behavior beyond those tests.