Data and benchmarks
Partial Credit That Keeps Difficult Robot Subtasks Visible
Fiatlux illustrates a gate-based evaluation in which unequal subtasks retain separate weights, incomplete conditions remain visible and unverified climbing stages are not mistaken for scored failures.
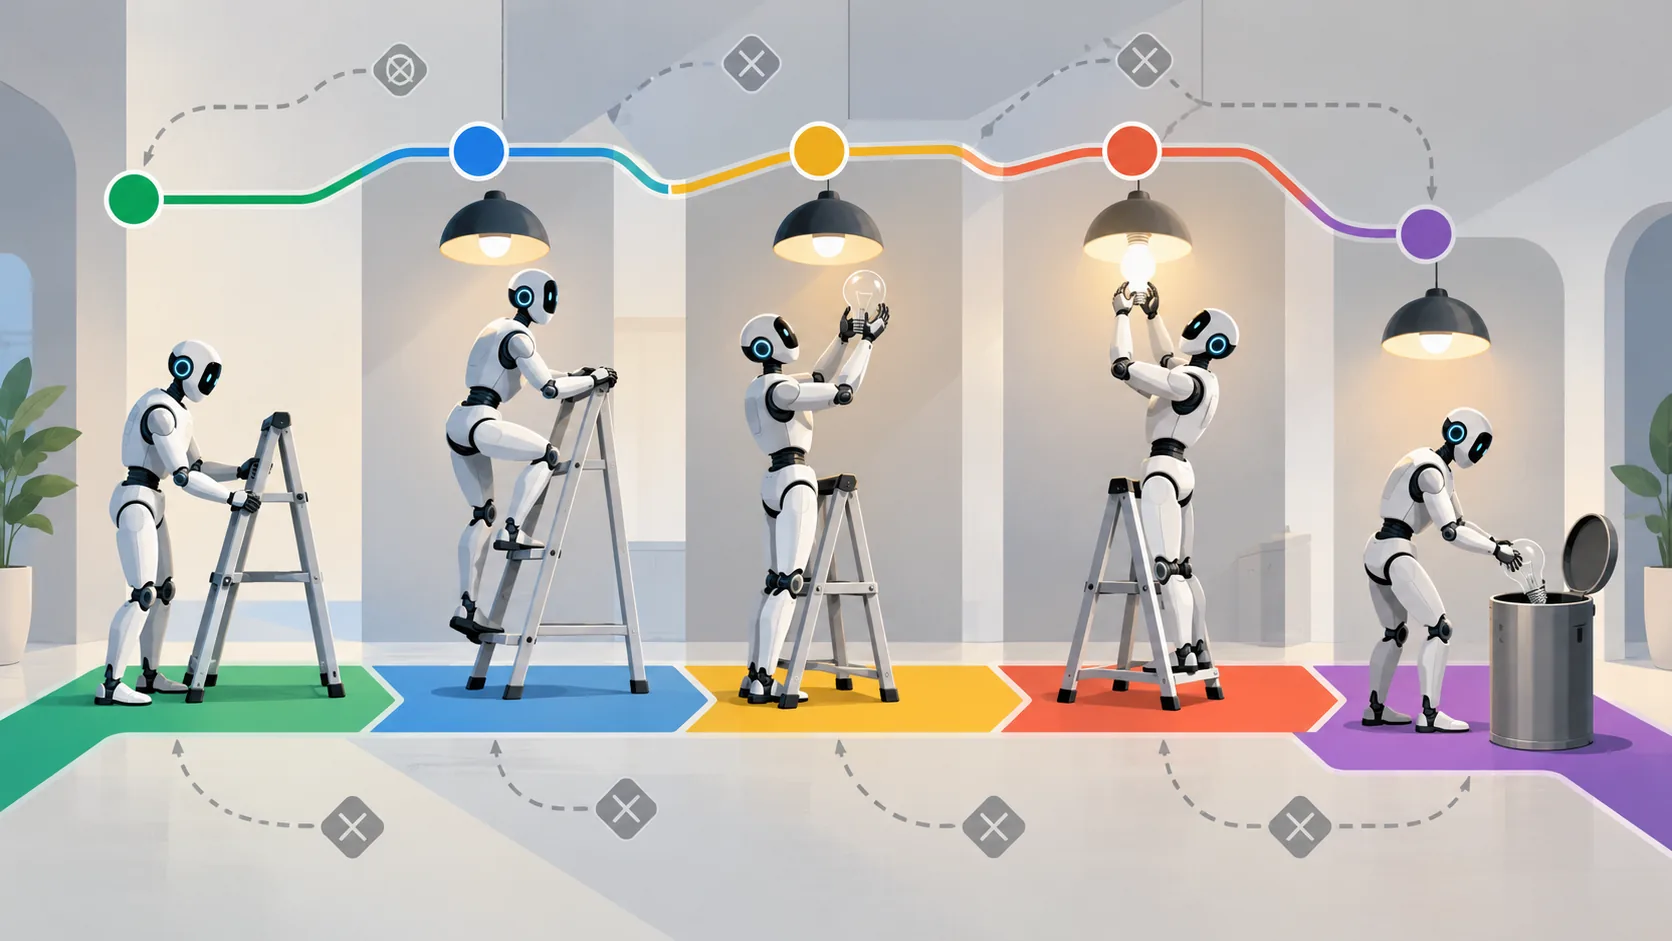
Fiatlux decomposes a simulated light-bulb replacement episode into subtask environments. The Unitree G1 humanoid must position a step ladder, climb it, exchange the bulb and place the spent bulb in a disposal crate without dropping either bulb or crossing a fragility bound. Because the authors regard these subtasks as unequal in difficulty, they assign difficulty weights instead of averaging their success rates.
Make progress visible inside each gate
Each Fiatlux success gate is a list of conditions that must all be satisfied for a full success. This structure distinguishes a run that meets some conditions from one that achieves none. A long-horizon benchmark can award partial credit without concealing hard failures by keeping difficulty-weighted results for each subtask and recording which conjunctive gate conditions were met, rather than averaging unequal subtask success rates.
A full success should remain stricter than partial progress. In the reported protocol, a take fires a gate only when every condition is satisfied and, where required, remains satisfied for a specified window. This prevents a transient state from counting as completion while still preserving evidence that the robot reached an intermediate condition.
Keep unverified subtasks separate from failures
The Fiatlux excerpt describes teleoperation as an achievability check. The climbing gates are marked as outstanding, not zero. For the associated examples, the robot is placed on the top tread through inverse kinematics and its leg joints are excluded from the action space, so those examples demonstrate that it can hold the on-ladder stance with and without the bulb; they do not demonstrate climbing.
Counting the four outstanding gates as achieved would overstate the available evidence, while assigning them zero would turn missing gate-firing demonstrations into observed failures. A benchmark report should therefore retain the status of each difficult subtask alongside any partial or aggregate score.
Test persistence, layouts and observation access
Fiatlux records takes across multiple layout seeds so that a gate cannot be credited solely because of one favorable spawn. Its evaluation also separates standard observations, defined as signals a physical robot could sense or estimate, from privileged observations containing exact simulator state. Results from those modes need to remain distinguishable because they give the evaluated systems different information.
The supported framework is therefore structural: decompose the episode, weight unequal subtasks, define full success through conjunctive conditions, retain partial condition satisfaction, enforce required persistence, vary layouts and label observation access. The available excerpt does not provide the exact arithmetic for combining the weights or say how individual satisfied conditions translate into a numerical fraction, so it is not sufficient to reproduce a specific Fiatlux aggregate score.