Embodied AI models
How HAF-VLA Sequences Walking, Posture and Manipulation
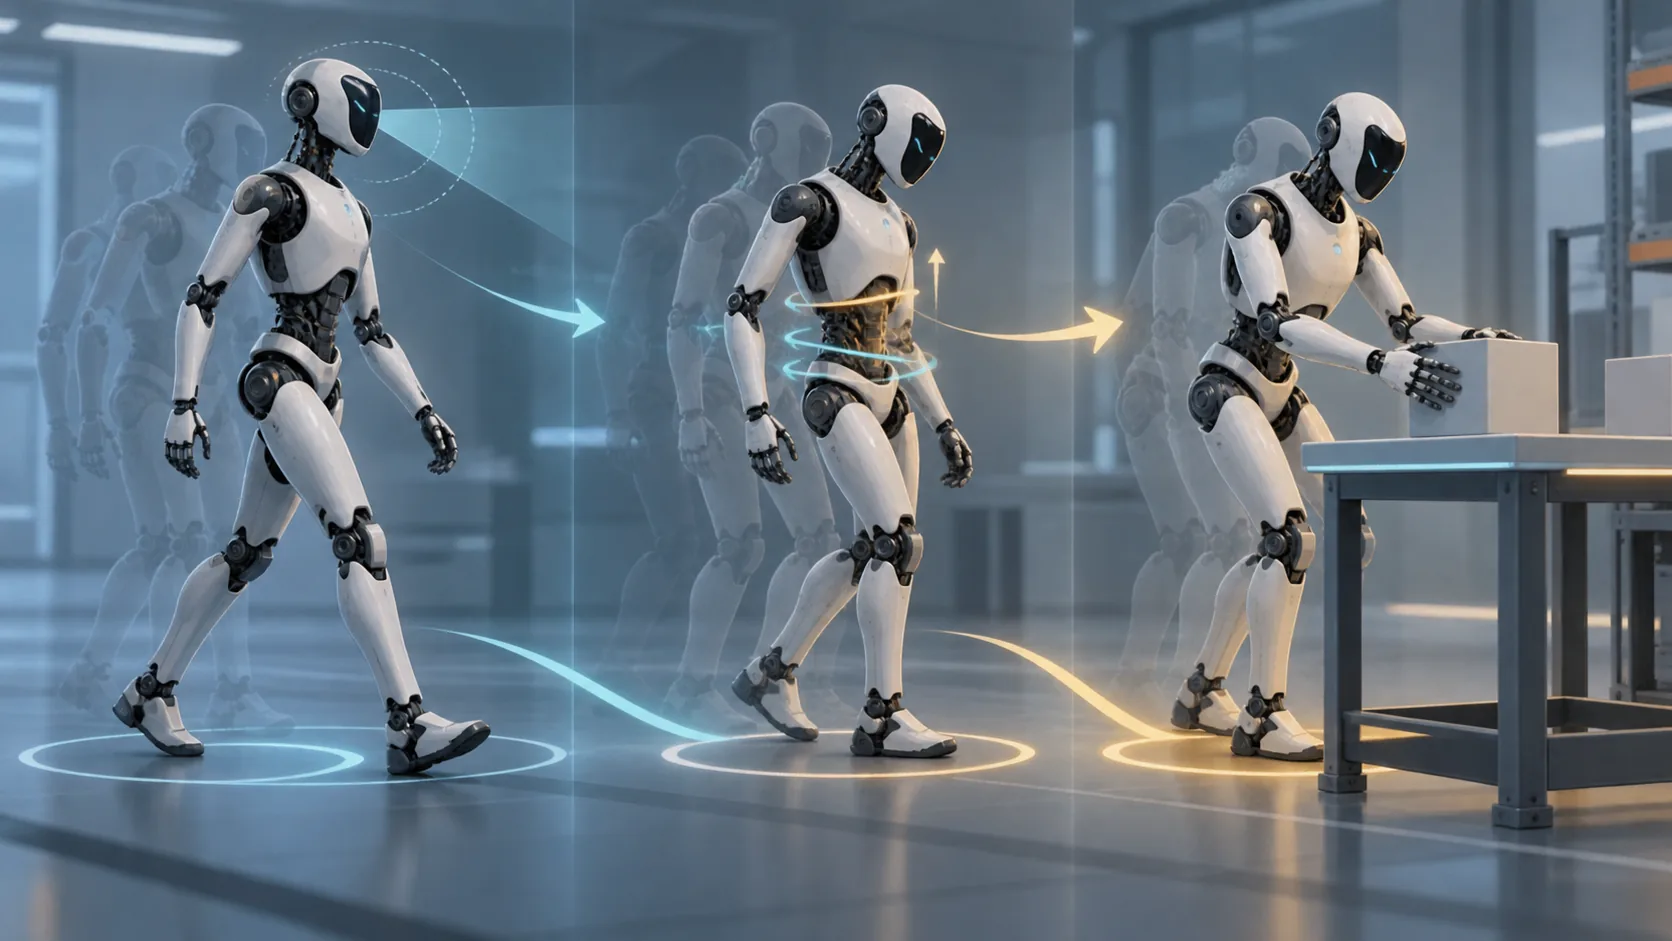
HAF-VLA generates an interdependent whole-body action in an ordered sequence, carrying earlier action representations forward to condition later control decisions.
Hierarchical action generation coordinates whole-body loco-manipulation by progressively denoising one shared action space in a fixed sequence: first locomotion and head commands, then waist refinement, and finally full-body manipulation. The HAF-VLA authors motivate this decomposition by noting that humanoids must jointly control locomotion, posture, gaze and manipulation, while inaccurate base or waist motion can prompt unstable, aggressive upper-body compensation.
HAF-VLA builds on a pretrained flow-matching vision-language-action model, retaining its vision-language prefix encoder and action-expert weights while adding learnable stage embeddings. Its cross-stage key-value cache carries action representations from each stage into the next, so waist control is conditioned on the preceding locomotion and head output, and the final manipulation stage can refine and augment the developing whole-body action rather than operate in isolation.
The authors report evaluating the framework on six real-world tasks and say it significantly improves existing models for humanoid loco-manipulation. The admitted preprint abstract, however, gives no task-level results, metrics or baseline details, so it supports the proposed coordination mechanism but not an independently confirmed performance advantage.