Embodied AI models
How PLaW-VLA Turns Latent Forecasts Into Robot Actions
The proposed policy feeds task-relevant latent forecasts into action generation while avoiding low-level visual reconstruction, with performance and latency figures reported by its authors.
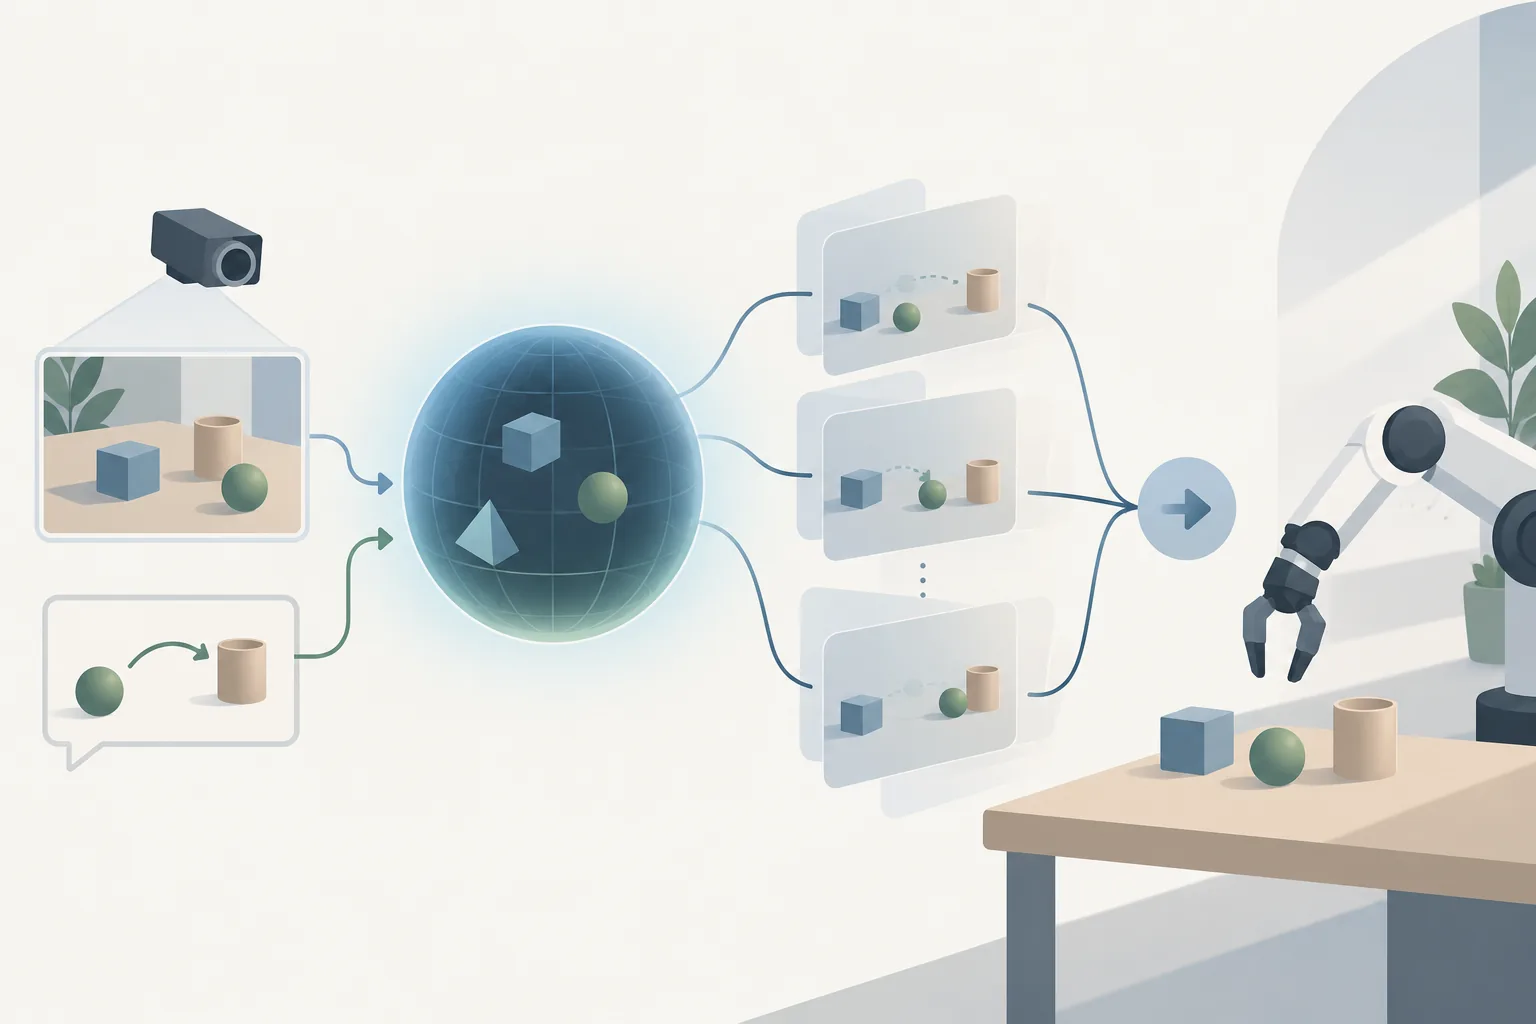
The preprint authors argue that predicting how the world evolves can provide useful context for long-horizon control, while the choice of future representation affects its effectiveness. In the authors' design, PLaW-VLA predicts task-relevant future states in a pretrained, prediction-oriented latent space and supplies them to the action generator alongside observation history and current task semantics. This representation reduces the need to predict visual details unrelated to control.
Built on a Mixture-of-Transformers architecture, PLaW-VLA uses structured causal attention to condition action generation on observation history, current task semantics and predicted future states.
The preprint authors report a +11.8 percentage-point gain over reactive policies on RoboTwin Hard Horizon III and a +1.77 percentage-point gain over reconstruction-oriented latent prediction on zero-shot LIBERO-Plus. They also report parallel future prediction and about 1/19 the inference latency of generative world-action modeling at comparable policy performance. These results are claims from the authors' abstract rather than independent confirmation; the reported comparisons connect task-relevant latent prediction with long-horizon control, generalization under distribution shift and lower inference latency.